> ## Documentation Index
> Fetch the complete documentation index at: https://docs.brightdata.com/llms.txt
> Use this file to discover all available pages before exploring further.
# 如何投递 Scraper API 结果
> 将 Bright Data Scraper API 结果投递到 webhook、Amazon S3、Google Cloud Storage 或 Snowflake。含投递目标对照表、IAM 与密钥配置以及 14 个 webhook 源 IP。
本指南介绍如何让 Bright Data Scraper API 任务将结果直接推送到您的基础设施,无需等待您手动下载。添加 `endpoint` 参数即可使用 webhook 投递,或一次性配置云端目标,让每个任务自动写入。所有抓取器的配置方式完全相同,只有 `dataset_id` 不同。
示例使用 Instagram 个人资料抓取器(`gd_l1vikfch901nx3by4`),按用户名发现个人资料。请从[异步请求页的对照表](/cn/products/scrapers/scrapers-library/async-requests)中替换为您所用平台的 `dataset_id`。
## 先决条件
* 拥有有效 API 密钥的 [Bright Data 账户](https://www.bright.cn/?hs_signup=1\&utm_source=docs)
* 熟悉[异步请求流程](/cn/products/scrapers/scrapers-library/async-requests)
* 使用 webhook 时,需要一个可公开访问的 HTTPS 端点(或 [webhook.site](https://webhook.site) 等测试工具)
* 使用云端目标时,需要在对应账户中创建凭据的权限:Amazon S3 需要 IAM 角色,Google Cloud 需要服务账号密钥,Snowflake 需要用户和角色
## 我应该选择哪个投递目标?
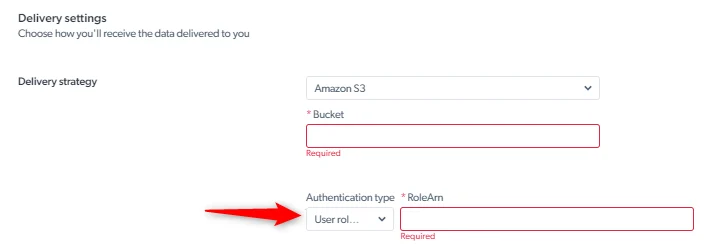
云端目标在控制面板中抓取器的 **Delivery settings** 标签页一次性设置;webhook 通过 `endpoint` 参数按请求设置。同一个任务可以同时使用两者。
| 目标 | 适用场景 | 配置 |
| :- | :- | :- |
| API 下载 | 测试和小型任务 | 无需配置。快照就绪后通过[下载快照](/cn/api-reference/scrapers/delivery-apis/download-snapshot)获取 |
| Webhook | 事件驱动的数据管道,负载小于 1 GB | 在触发请求中传入 `endpoint` 查询参数。见下文 webhook 投递 |
| Amazon S3 | 大体积负载、数据湖、长期留存 | 一次性创建 IAM 策略和角色。见下文 S3 投递 |
| Google Cloud Storage | Google Cloud 数据平台 | 一次性创建服务账号密钥。见下文 Google Cloud Storage 投递 |
| Snowflake | 直接加载到数据仓库 | 一次性准备数据库、stage、角色和用户。见下文 Snowflake 投递 |
| Google Cloud Pub/Sub | 消息驱动的数据管道 | 在控制面板中输入主题和凭据 |
| Microsoft Azure Storage | Azure 数据平台 | 在控制面板中输入容器和凭据 |
| SFTP 或 FTP | 没有云 API 的服务器 | 在控制面板中输入主机、路径和凭据 |
## 支持哪些输出格式
Scraper API 的输出格式为 NDJSON(默认)、JSON、JSON lines、CSV 和 Parquet。每种格式都有对应的 API 值,但并非每个值在所有位置都可用:
| 格式 | API 值 | `/scrape` 的 `format` | `/trigger` 的 `format` | `deliver.filename.extension` |
| :- | :- | :- | :- | :- |
| NDJSON(默认) | `ndjson` | 是 | 是 | 是 |
| JSON | `json` | 是 | 是 | 是 |
| JSON lines | `jsonl` | 是 | 是 | 是 |
| CSV | `csv` | 是 | 是 | 是 |
| Parquet | `parquet` | 未列出 | 未列出 | 是 |
不带 `format` 的 `/scrape` 请求或快照下载返回 NDJSON,每行一条记录。如需 JSON 数组,请设置 `format=json`。2026 年 9 月 30 日验证。
“未列出”表示该值不在该参数的 API 规范中。NDJSON 和 JSON lines 是两个独立的 API 值:`ndjson` 和 `jsonl`。
## 什么是流式投递和文件投递
流式投递和文件投递会改变投递内容:
* **流式投递**在任务运行期间以每批 10 到 100,000 行发送结果,而不是在任务结束时发送一个文件。
* **文件投递**在记录旁附上每个页面的原始 HTML、WARC 或截图。
两者都需要存储或 webhook 目标,不能使用 API 下载。详见[如何流式传输结果并投递文件](/cn/products/scrapers/scrapers-library/stream-and-file-delivery)。
## 如何将结果投递到 webhook
当您在触发异步采集时提供 `endpoint` URL,任务完成后 Bright Data 会向该 URL 发送包含抓取数据的 `POST` 请求,无需轮询。
```text theme={null}
您的应用 --> POST /trigger(带 webhook URL)--> Bright Data 抓取 --> POST 到您的 webhook
```
### 步骤 1:设置测试 webhook
测试时,可使用 [webhook.site](https://webhook.site) 获取临时公开 URL:
1. 在浏览器中打开 [webhook.site](https://webhook.site)
2. 复制页面显示的专属 URL(例如 `https://webhook.site/abc-123-def`)
3. 保持页面开启以监控收到的请求
### 步骤 2:使用 webhook URL 触发采集
在异步 `/trigger` 请求中添加 `endpoint` 查询参数:
```bash cURL theme={null}
curl -H "Authorization: Bearer YOUR_API_KEY" \
-H "Content-Type: application/json" \
-d '{"input":[{"user_name":"zoobarcelona"}],"limit_per_input":null}' \
"https://api.brightdata.com/datasets/v3/trigger?dataset_id=gd_l1vikfch901nx3by4¬ify=false&include_errors=true&type=discover_new&discover_by=user_name&endpoint=https://webhook.site/abc-123-def&uncompressed_webhook=true"
```
```python Python (requests) theme={null}
import requests
response = requests.post(
"https://api.brightdata.com/datasets/v3/trigger",
params={
"dataset_id": "gd_l1vikfch901nx3by4",
"notify": "false",
"include_errors": "true",
"type": "discover_new",
"discover_by": "user_name",
"endpoint": "https://webhook.site/abc-123-def",
"uncompressed_webhook": "true",
},
headers={"Authorization": "Bearer YOUR_API_KEY"},
json={"input": [{"user_name": "zoobarcelona"}], "limit_per_input": None},
)
snapshot = response.json()
print("Snapshot ID:", snapshot["snapshot_id"])
```
```javascript Node.js (Axios) theme={null}
import axios from "axios";
const response = await axios.post(
"https://api.brightdata.com/datasets/v3/trigger",
{ input: [{ user_name: "zoobarcelona" }], limit_per_input: null },
{
params: {
dataset_id: "gd_l1vikfch901nx3by4",
notify: false,
include_errors: true,
type: "discover_new",
discover_by: "user_name",
endpoint: "https://webhook.site/abc-123-def",
uncompressed_webhook: true,
},
headers: { Authorization: "Bearer YOUR_API_KEY" },
}
);
console.log("Snapshot ID:", response.data.snapshot_id);
```
```javascript Node.js (fetch) theme={null}
const params = new URLSearchParams({
dataset_id: "gd_l1vikfch901nx3by4",
notify: "false",
include_errors: "true",
type: "discover_new",
discover_by: "user_name",
endpoint: "https://webhook.site/abc-123-def",
uncompressed_webhook: "true",
});
const response = await fetch(`https://api.brightdata.com/datasets/v3/trigger?${params}`, {
method: "POST",
headers: {
"Authorization": "Bearer YOUR_API_KEY",
"Content-Type": "application/json",
},
body: JSON.stringify({ input: [{ user_name: "zoobarcelona" }], limit_per_input: null }),
});
const snapshot = await response.json();
console.log("Snapshot ID:", snapshot.snapshot_id);
```
关键参数:
| 参数 | 说明 |
| :- | :- |
| `endpoint` | 接收 `POST` 负载的 HTTP 端点 URL |
| `uncompressed_webhook` | 设为 `true` 可接收未压缩的 JSON(默认为 gzip) |
| `format` | 输出格式:`json`、`ndjson`、`jsonl` 或 `csv`。见[输出格式](#支持哪些输出格式) |
### 步骤 3:验证投递
采集完成后(少量记录通常需 30 到 60 秒),查看您的 webhook.site 页面,应能看到一条包含抓取数据的 `POST` 请求。
该负载与直接通过 API 下载得到的 JSON 数组相同:
每条记录是一个 Instagram 个人资料。字段见[按用户名发现的响应示例](/cn/api-reference/scrapers/social-media-apis/instagram-profiles-discover-by-username)。
### 如何在生产环境中处理 webhook
在生产环境中,请将 `endpoint` URL 指向您自己的服务器端点。
```javascript server.js theme={null}
const express = require("express");
const app = express();
app.use(express.json({ limit: "100mb" }));
app.post("/webhook/scraper", (req, res) => {
const records = req.body;
console.log(`Received ${records.length} records`);
for (const record of records) {
console.log(`- ${record.account}`);
}
res.status(200).json({ received: true });
});
app.listen(3000, () => console.log("Webhook server running on port 3000"));
```
```python server.py theme={null}
from flask import Flask, request, jsonify
app = Flask(__name__)
@app.route("/webhook/scraper", methods=["POST"])
def handle_webhook():
records = request.get_json()
print(f"Received {len(records)} records")
for record in records:
print(f"- {record.get('account')}")
return jsonify({"received": True}), 200
if __name__ == "__main__":
app.run(port=3000)
```
请在 30 秒内返回 `200` 状态码以确认接收。如果您的端点失败或超时,Bright Data 会重试投递。
### 如何为 webhook 投递添加鉴权
如果您的端点需要鉴权,请添加 `auth_header` 参数。Bright Data 会将其值作为 `Authorization` 标头随每次投递发送到该端点。已于 2026 年 9 月 7 日验证。本页早期版本将该参数写作 `webhook_header_Authorization`;API 会忽略该名称并在投递时不带 `Authorization` 标头,如果您复制过该写法,请替换。
```bash theme={null}
curl -H "Authorization: Bearer YOUR_API_KEY" \
-H "Content-Type: application/json" \
-d '{"input":[{"user_name":"zoobarcelona"}],"limit_per_input":null}' \
"https://api.brightdata.com/datasets/v3/trigger?dataset_id=gd_l1vikfch901nx3by4¬ify=false&include_errors=true&type=discover_new&discover_by=user_name&endpoint=https://your-server.com/webhook&auth_header=Bearer+YOUR_SECRET_TOKEN"
```
### 投递请求带有哪些标头?
每次 webhook 投递都是一个 `POST` 请求,带有 `Content-Type: application/json; charset=utf-8`、以 `BRD dca-stage-deliver` 开头的 `User-Agent`、存放快照 ID 的 `dca-collection-id` 标头以及标明文件名的 `dca-filename` 标头。请使用 `dca-collection-id` 将投递与任务对应,而不是解析请求体。于 2026 年 9 月 7 日观察到。
### webhook 来自哪些 IP?
如果您的服务器使用 IP 允许列表,请添加以下 14 个 Bright Data webhook 源 IP。Bright Data 的所有异步 webhook 投递(涵盖 Scraper API、AI 爬虫和 SERP API)都来自其中之一。
```text theme={null}
54.175.27.69
34.225.9.175
100.28.38.247
100.29.18.195
52.72.185.255
35.174.112.248
54.165.183.124
3.91.140.7
52.202.75.37
98.82.225.117
100.27.150.189
18.214.10.85
35.169.71.210
44.194.183.74
```
## 如何将结果投递到 Amazon S3
先一次性配置 IAM 角色,然后在每个需要写入存储桶的 `/trigger` 请求中添加 `deliver` 配置。
### 步骤 1:创建 IAM 策略和角色
Bright Data 通过担任您 AWS 账户中的 IAM 角色向存储桶写入。创建允许写入的策略、Bright Data 投递角色可以担任的角色,并将角色附加到存储桶。
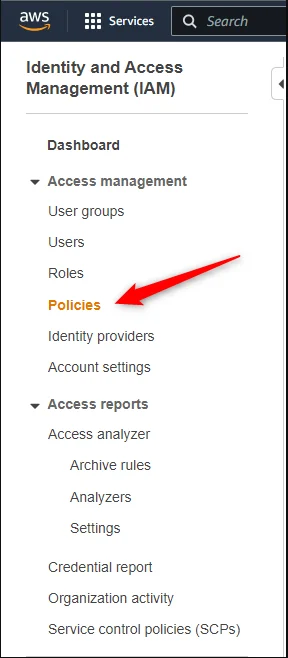
 在 IAM 控制台打开**策略**,创建允许对存储桶执行 `PutObject` 和 `GetObject` 的策略。
 ```json theme={null}
{
"Version": "2012-10-17",
"Statement": [
{
"Effect": "Allow",
"Action": ["s3:PutObject", "s3:GetObject"],
"Resource": "arn:aws:s3:::NAME-OF-YOUR-BUCKET/*"
}
]
}
```
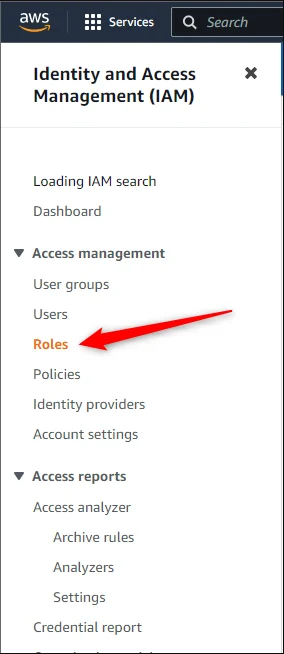
打开**角色**,创建角色,并在**权限策略**下附加第 1 步的策略。记下角色的 ARN,形如 `arn:aws:iam:::role/`,需填入 `credentials.role_arn`。
 角色的信任策略允许 Bright Data 的投递角色担任它。条件中的外部 ID 即您作为 `credentials.external_id` 发送的值:
```json theme={null}
{
"Version": "2012-10-17",
"Statement": [
{
"Effect": "Allow",
"Principal": {
"AWS": "arn:aws:iam::422310177405:role/brd.ec2.zs-dca-delivery"
},
"Action": "sts:AssumeRole",
"Condition": {
"StringEquals": {
"sts:ExternalId": "YOUR EXTERNAL ID"
}
}
}
]
}
```
在存储桶上通过 ARN 授予第 2 步创建的角色访问权限。
### 步骤 2:使用 S3 `deliver` 配置触发采集
在 `/trigger` 请求体中与 `input` 并列添加 `deliver` 对象。Bright Data 会将此任务的结果写入您的存储桶:
```bash theme={null}
curl -H "Authorization: Bearer YOUR_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"input": [{"user_name": "zoobarcelona"}],
"limit_per_input": null,
"deliver": {
"type": "s3",
"bucket": "your-bucket-name",
"credentials": {
"role_arn": "arn:aws:iam:::role/",
"external_id": "YOUR_EXTERNAL_ID"
},
"filename": {"template": "{[snapshot_id]}", "extension": "json"}
}
}' \
"https://api.brightdata.com/datasets/v3/trigger?dataset_id=gd_l1vikfch901nx3by4¬ify=false&include_errors=true&type=discover_new&discover_by=user_name"
```
| `deliver` 字段 | 说明 |
| :- | :- |
| `type` | `s3` |
| `bucket` | 您的 S3 存储桶名称。必填 |
| `credentials` | 步骤 1 中的 `role_arn` 和 `external_id`。也可以使用 access keys:`aws-access-key` 和 `aws-secret-key` |
| `endpoint_url` | 兼容 S3 的存储的主机地址。仅适用于 access keys |
| `region` | 您的 S3 存储桶所在区域 |
| `filename.template` | 文件名,可包含 `{[snapshot_id]}` 等占位符。必填 |
| `filename.extension` | 文件格式,例如 `json`、`csv` 或 `parquet`。必填。见[输出格式](#支持哪些输出格式) |
### 步骤 3:验证投递
采集完成后,检查 S3 存储桶中是否已有投递文件:
```bash theme={null}
aws s3 ls s3://your-bucket-name/
```
您应能看到以快照 ID 命名的文件(例如 `sd_m1a2b3c4d5e6f7g8h.json`)。下载并查看:
```bash theme={null}
aws s3 cp s3://your-bucket-name/sd_m1a2b3c4d5e6f7g8h.json ./results.json
cat results.json | python -m json.tool | head -20
```
您也可以使用 [Monitor Delivery API](/cn/api-reference/scrapers/management-apis/monitor-delivery) 查看投递状态。
## 如何将结果投递到 Google Cloud Storage
Google Cloud Storage 投递使用服务账号密钥进行身份验证。创建密钥后,将其中的私钥粘贴到抓取器的投递设置中。
1. 打开 [Google Cloud 控制台](https://console.cloud.google.com/),展开菜单并打开 **IAM 和管理**。
2. 点击**服务账号**。
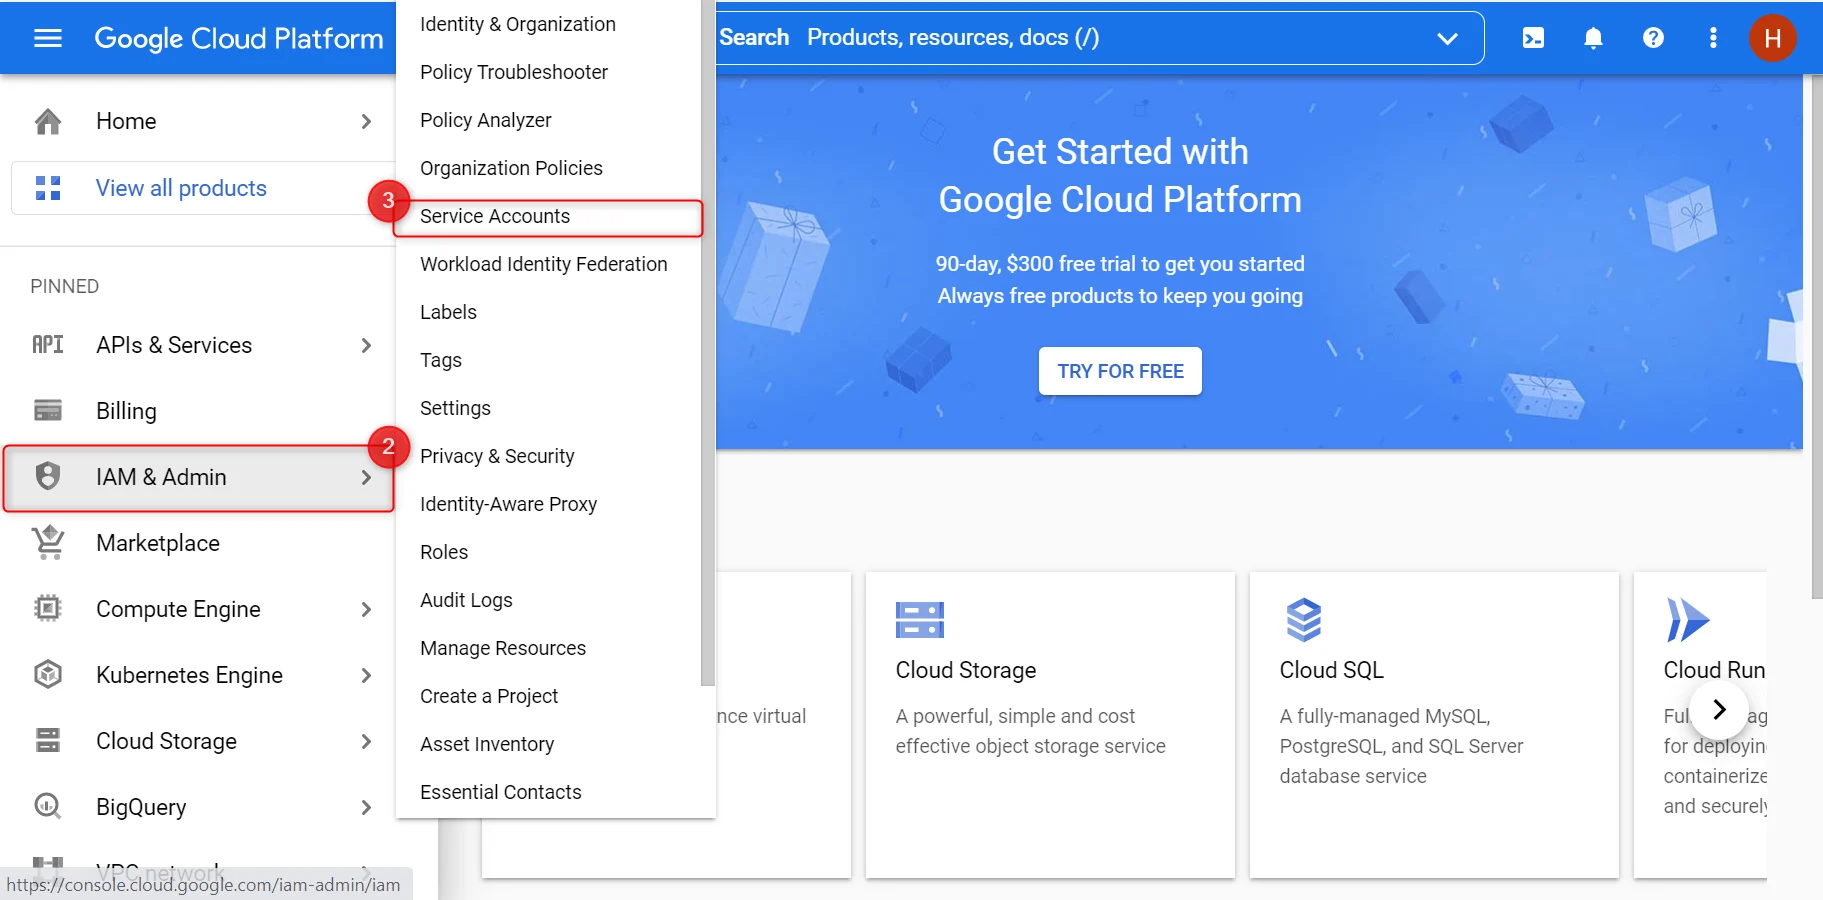 3. 选择已有服务账号或新建一个。如果没有该按钮,请先创建项目。
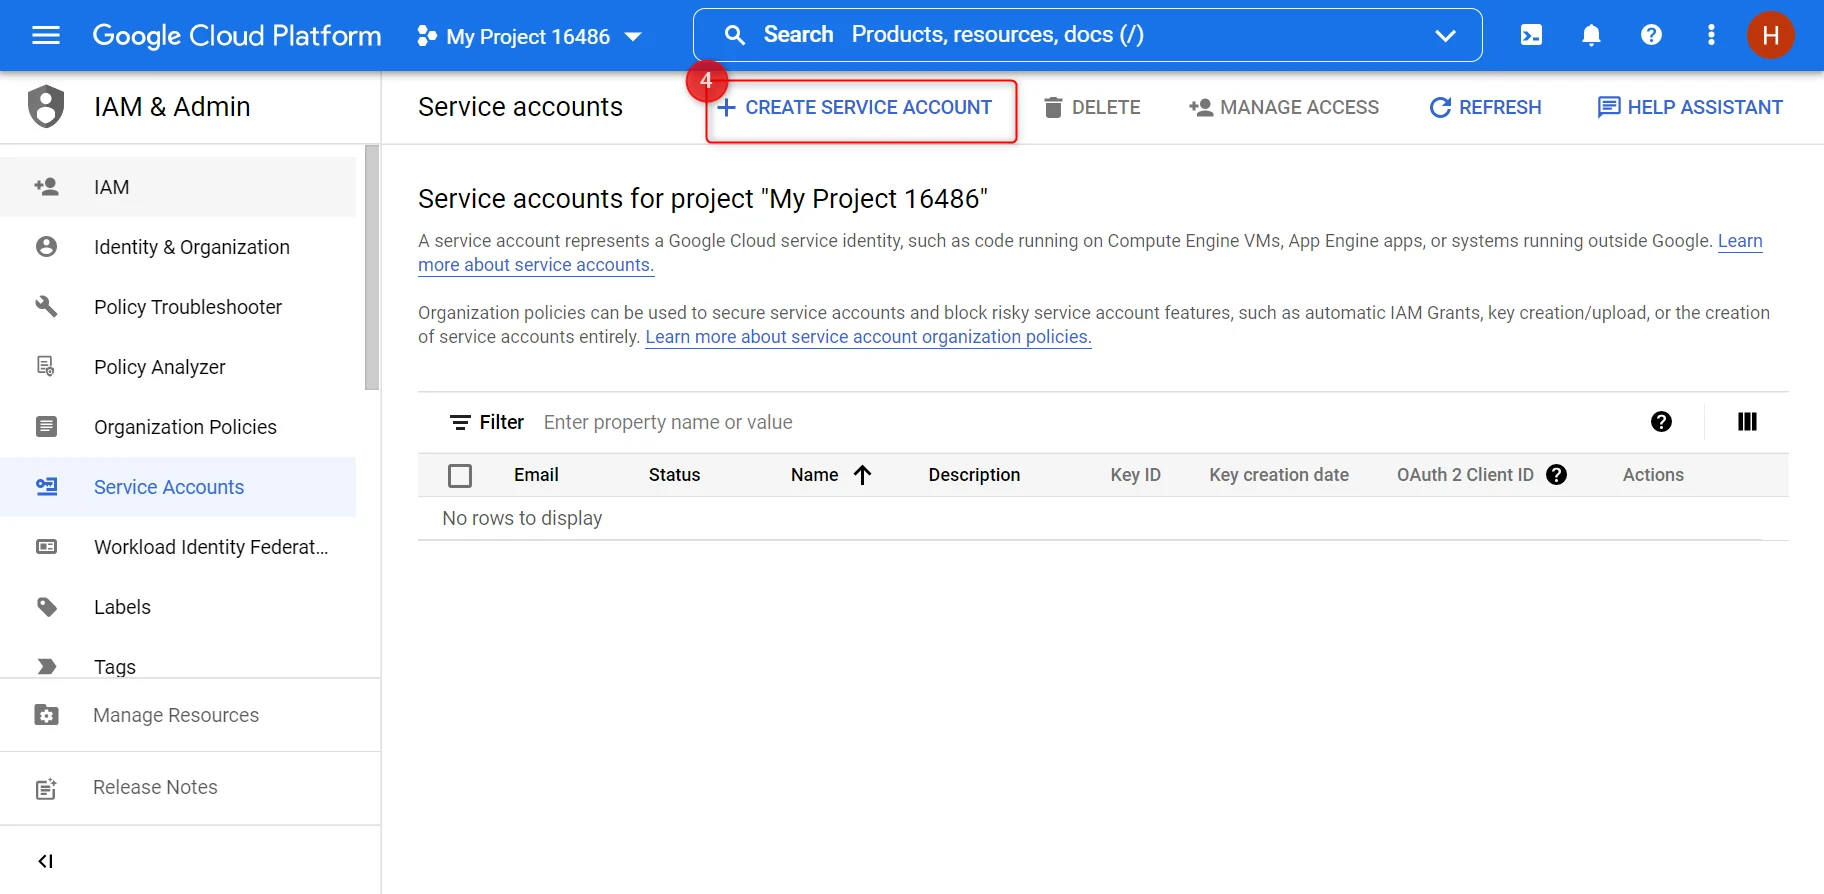
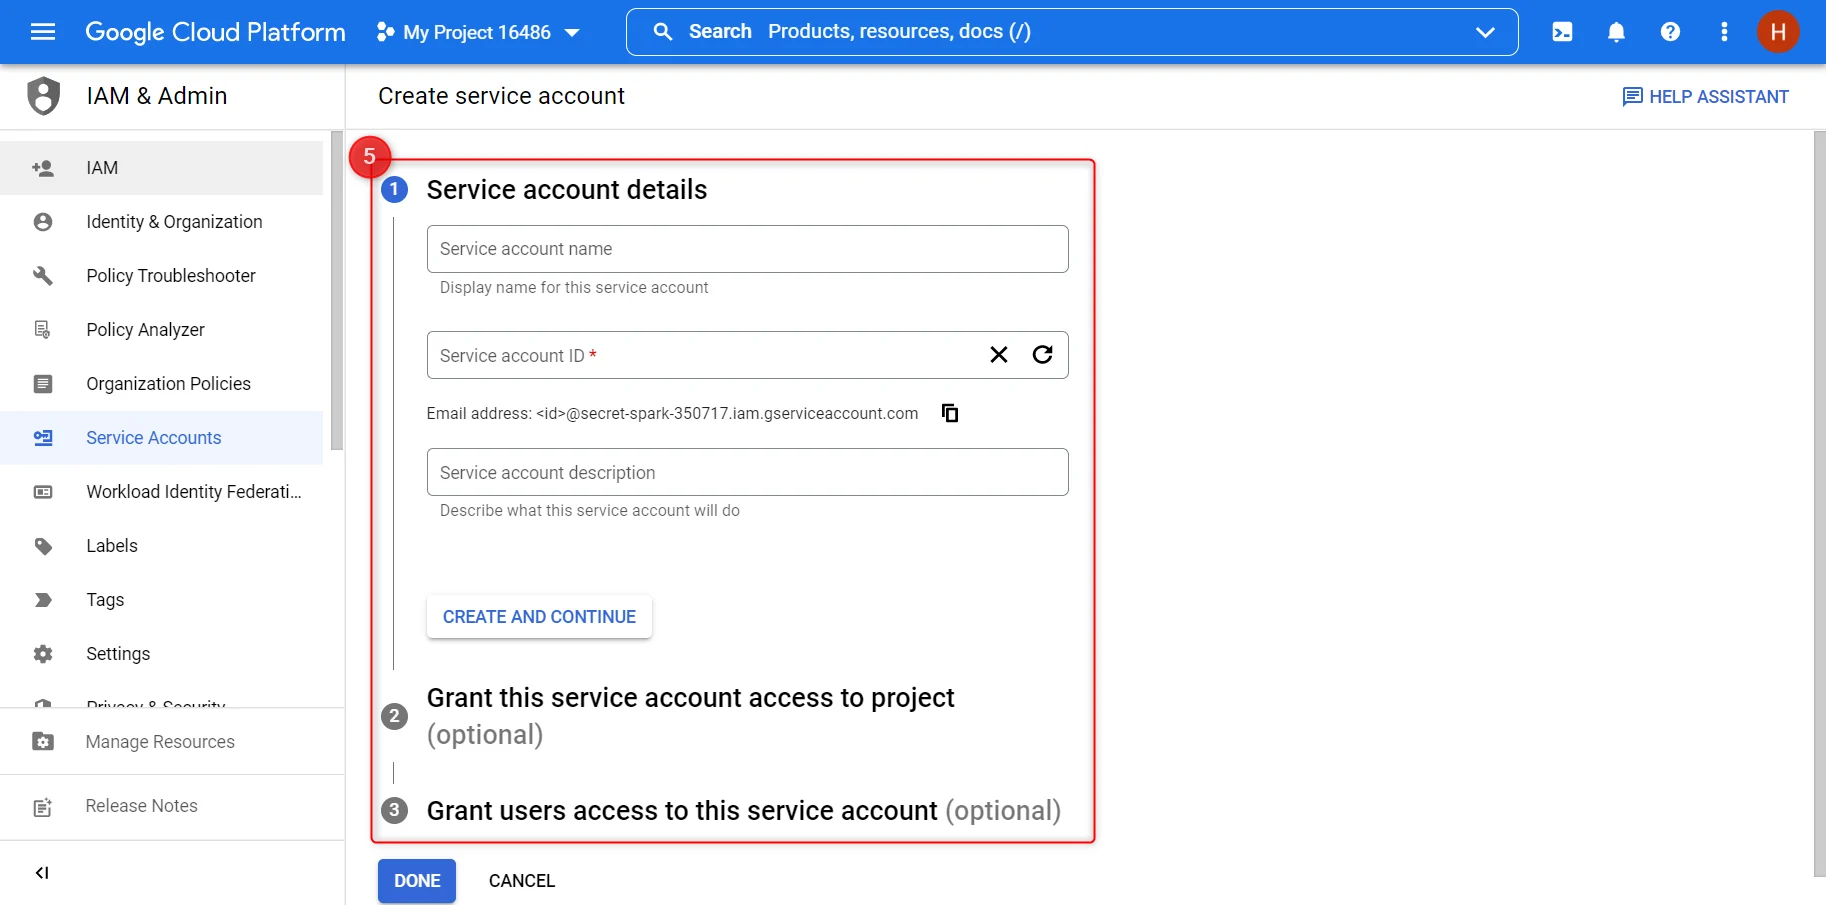
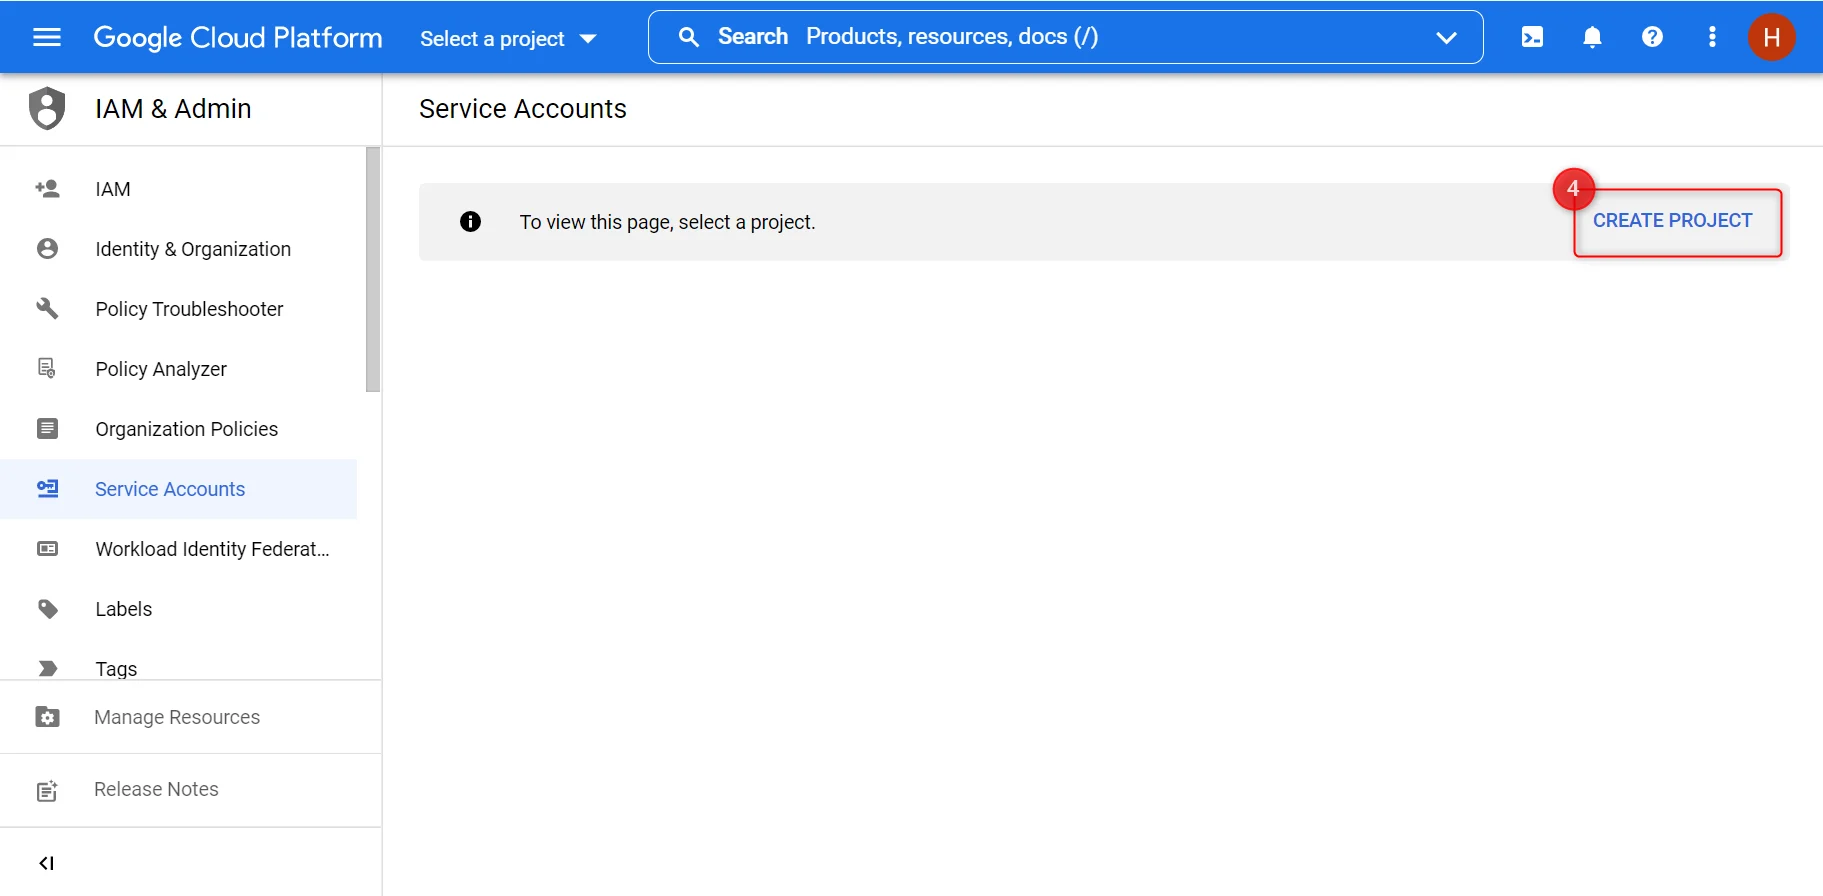 4. 输入名称、ID 和说明,授予账号访问存储桶的权限,然后创建。
 5. 点击服务账号的邮箱地址。
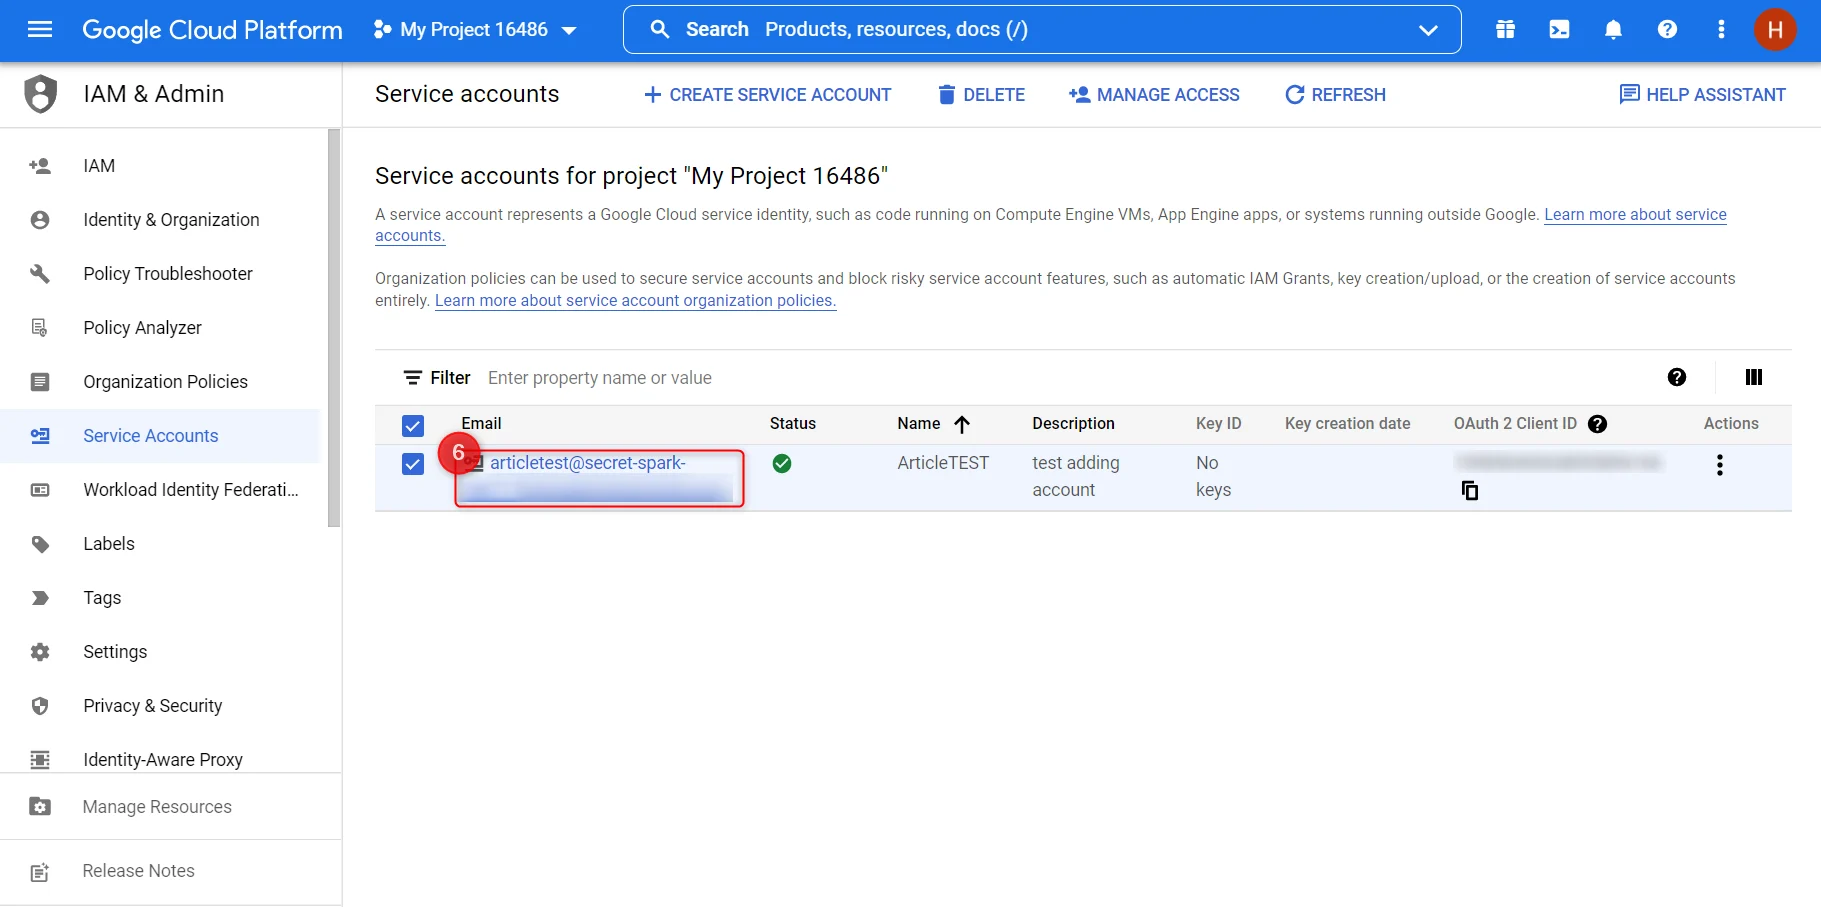 6. 打开**密钥**标签页,点击**添加密钥**,再点击**创建新密钥**。
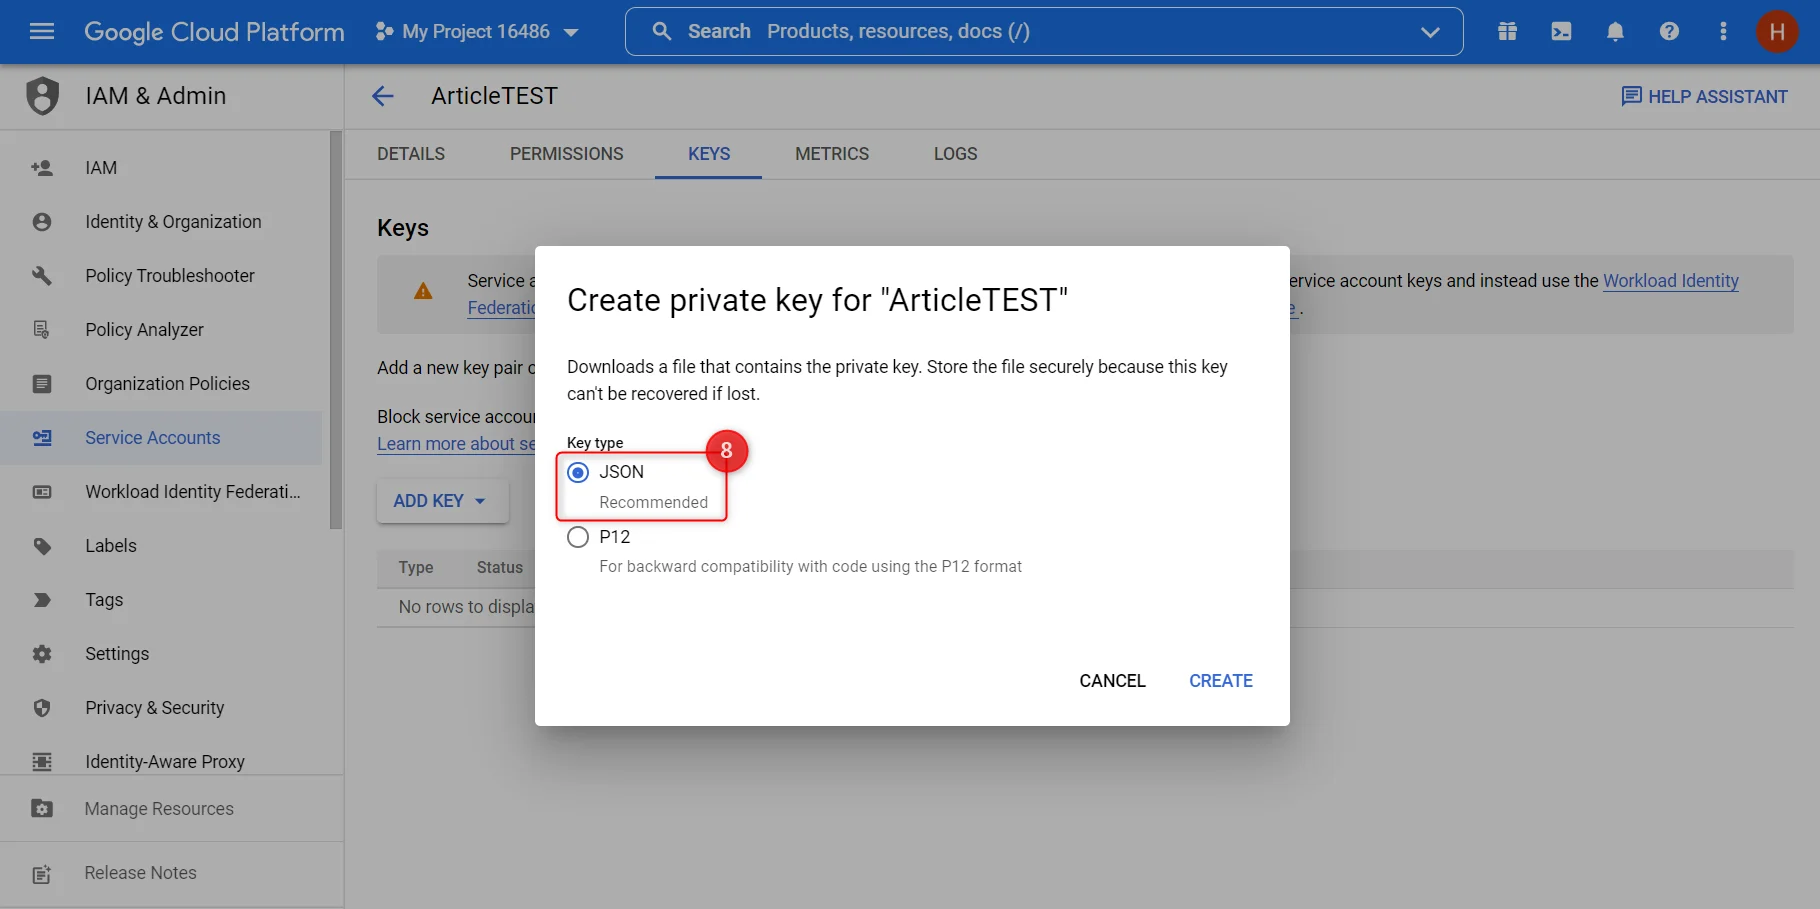
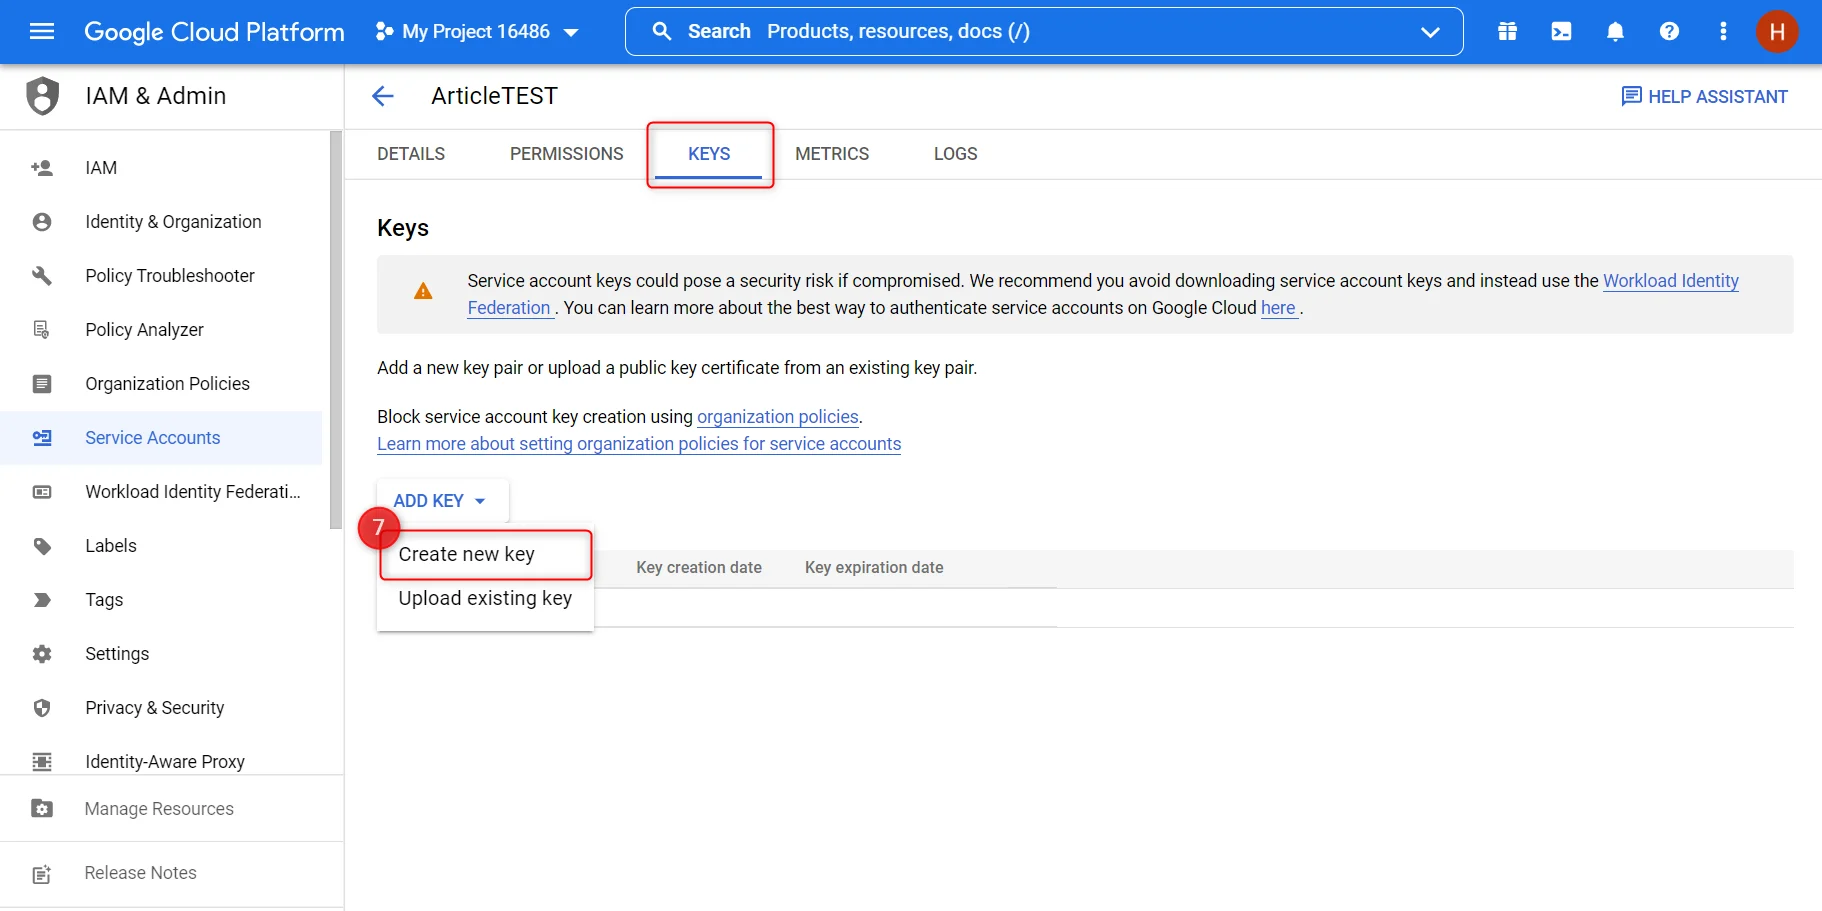 7. 选择 **JSON**。密钥文件会下载到您的计算机。
 8. 将下载文件中的 `private_key` 值复制到抓取器的投递设置中,并填写存储桶名称和文件格式。
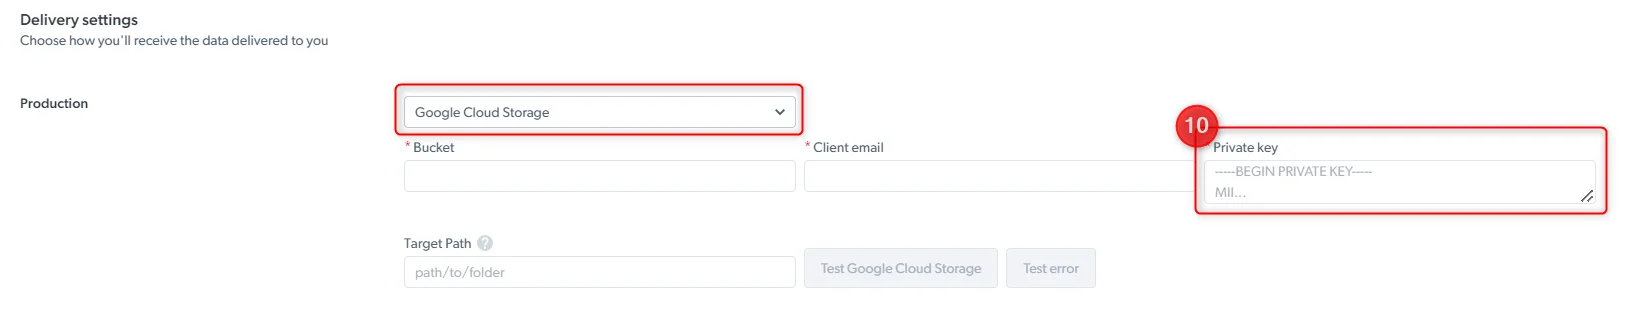 按常规方式触发采集,结果会自动写入存储桶,无需额外参数。
## 如何将结果投递到 Snowflake
Bright Data 通过内部命名 stage 加载数据,使用您为其创建的用户和角色。在您的 Snowflake 账户中运行以下命令,然后在抓取器的投递设置中填入这些值。
```sql theme={null}
CREATE DATABASE ;
```
每个数据库都有 `PUBLIC` schema。若要使用其他 schema:
```sql theme={null}
CREATE SCHEMA ;
```
Snowflake 关于数据加载仓库大小的建议同样适用;参见 [Warehouses overview](https://docs.snowflake.com/en/user-guide/warehouses-overview#impact-on-data-loading)。
```sql theme={null}
CREATE WAREHOUSE ;
```
```sql theme={null}
CREATE STAGE ;
```
```sql theme={null}
CREATE ROLE ;
GRANT OPERATE ON WAREHOUSE TO ROLE ;
GRANT WRITE ON STAGE TO ROLE ;
```
```sql theme={null}
CREATE USER
PASSWORD = ''
LOGIN_NAME =
MUST_CHANGE_PASSWORD = FALSE
DISABLED = FALSE
COMMENT = 'user for Bright Data to upload data directly into Snowflake';
GRANT ROLE TO USER ;
```
如果账户启用了[网络策略](https://docs.snowflake.com/en/user-guide/network-policies),请添加以下四个地址:
```sql theme={null}
ALTER NETWORK POLICY
SET ALLOWED_IP_LIST=(
,
'35.169.71.210',
'34.233.211.38',
'44.194.183.74',
'54.243.177.151');
```
在抓取器的投递设置中输入数据库、schema、仓库、stage、用户和密码。如需设置帮助,请联系[支持团队](mailto:support@brightdata.com)。
## 故障排除
### Webhook 收不到数据?
* 确认该 URL 可公开访问(不能是 `localhost`)
* 确认您的端点在 30 秒内返回 `200` 状态码
* 如果有防火墙规则,请确认上述 14 个 webhook IP 已加入允许列表
### 收到的是压缩数据?
若省略 `uncompressed_webhook=true`,数据将以 gzip 压缩形式送达。请在触发 URL 中添加 `uncompressed_webhook=true`,或在服务器端解压负载。
### 负载超出服务器处理能力?
大型采集的负载最高可达 1 GB。请在 Express.js 中设置 `express.json({ limit: "100mb" })`,或在您所用框架中做等效配置。对于超大数据集,请改用 S3 投递。
### S3 中没有出现文件?
* 确认 IAM 角色 ARN 和外部 ID 正确
* 确认存储桶策略允许来自 Bright Data 账户的 `s3:PutObject`
* 确认存储桶区域与配置一致
* 在 Bright Data 控制面板的 **Logs** 中查看投递状态
### S3 出现 Access denied 错误?
请确认 IAM 角色的信任策略指向 Bright Data 账户 `422310177405` 中的投递角色,且信任策略中的外部 ID 与您发送的 `external_id` 一致。
## 常见问题
### 各平台的投递配置有区别吗?
没有区别。所有 Bright Data 抓取器的 webhook 参数和云端目标配置完全相同,只有触发请求中的 `dataset_id` 不同。
### 可以同时使用 webhook 和云存储吗?
可以。云端投递在控制面板中按抓取器配置,而 `endpoint` 参数按请求设置,因此单个任务可同时使用两者。
### 任务完成时我的 webhook 不可用会怎样?
Bright Data 会重试投递。如果您的端点持续不可用,可使用触发调用返回的 `snapshot_id` 直接下载快照,快照保留 30 天。
## 相关内容
* [如何使用异步请求批量抓取数据](/cn/products/scrapers/scrapers-library/async-requests)
* [如何流式传输结果并投递文件](/cn/products/scrapers/scrapers-library/stream-and-file-delivery)